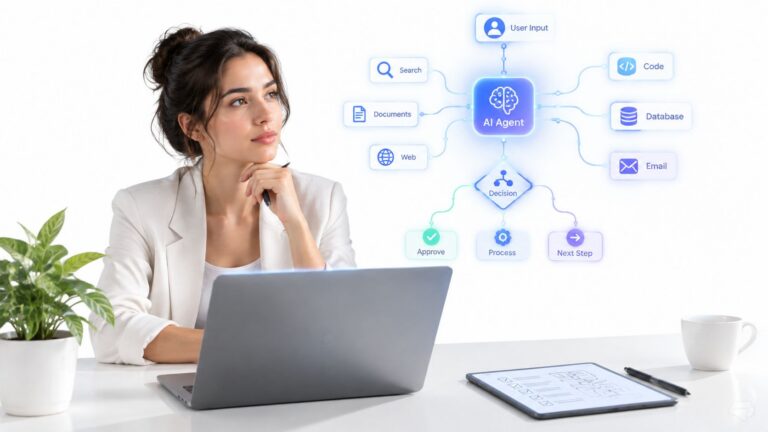
An AI agent is worth it when a workflow runs often, branches into several decisions, crosses systems, has a cost you can measure, and can recover safely from mistakes. When one rule covers most cases, I use a script. When the task needs language but changes no records, a chatbot is enough. Rare, high-stakes calls stay human.
You're probably looking at an AI agent because a workflow is eating your week. Support tickets pile up, leads wait for routing, research sprawls across tabs, and every vendor promises that autonomy will fix it. The uncomfortable question is whether you need an agent at all.
I'm Samuel Woods. I look for the point where AI creates an opportunity, then build the workflow that captures it. My rule is simple: use an agent when the work is repetitive, multi-step, measurable, and safe enough to recover when it makes a mistake. Everything else starts with a script, a chatbot, or a human.
The market has moved beyond demos. In PwC's May 2025 survey of 300 senior executives, 79% said AI agents were already being adopted, 88% planned to increase AI-related budgets, and 66% of adopters reported measurable productivity gains because of agents, as reported in PwC's AI agent survey. That doesn't mean every small business needs one. It means the right workflow can justify the expense.
Table of Contents
- The Moment You Almost Bought an Agent You Didn't Need
- What an AI Agent Actually Is, Without the Hype
- Business Signals That Justify an AI Agent
- Agents vs Chatbots, Scripts, and Human-Only Work
- A Readiness Framework You Can Run This Week
- When AI Agents Are the Wrong Default
- Your Monday Checklist and Governance Guardrails
The Moment You Almost Bought an Agent You Didn't Need
A 14-person direct-to-consumer brand came to a discovery call with a $14,000 problem. Its founder had approved an agentic AI tier from a software vendor to automate returns. The proposed system would read tickets, inspect orders, apply policy, issue refunds, and escalate exceptions.
The workflow sounded advanced. The underlying queue wasn't.
A quick review showed that 71% of tickets came from two recurring SKUs. One rule could identify those orders and return the correct response in 200 milliseconds. The founder was close to signing a $9,000 annual AI agent license. A $40 Zapier table could have closed the same loop, with less setup and easier debugging.
The mistake wasn't buying AI. The mistake was paying for judgment where a deterministic rule already existed.
A B2B founder avoided the same trap by mapping volume before looking at vendors. He listed every inbound request, counted the decision branches, noted the systems involved, and attached a cost to each resolution. The result was a small automation for routine requests, a chatbot for questions that needed language understanding, and an agent only for the cross-system cases that required judgment.
My decision rule: adopt an agent when a workflow crosses 500 weekly interactions, has at least three decision branches, creates a measurable downstream cost, and connects to APIs you can debug on a Friday afternoon.
Those thresholds are my operating filter, not a law of nature. If a single template solves most cases, you don't need an agent. If the workflow happens rarely and every action carries serious consequences, you probably need a human.
What being wrong costs
Agent software can cost $200 to $2,000 per month, before you account for integration work and the maintenance burden that follows. Treat that range as a rough budgeting assumption and replace it with real quotes before you commit.The primary expense is integration debt: permissions, broken fields, undocumented edge cases, and the time you spend reconstructing why an action happened.
The question behind when to use AI agents is therefore operational readiness. Enthusiasm doesn't make an agent safe. A stable workflow, inspectable data, controlled permissions, and a recovery path do.
What an AI Agent Actually Is, Without the Hype
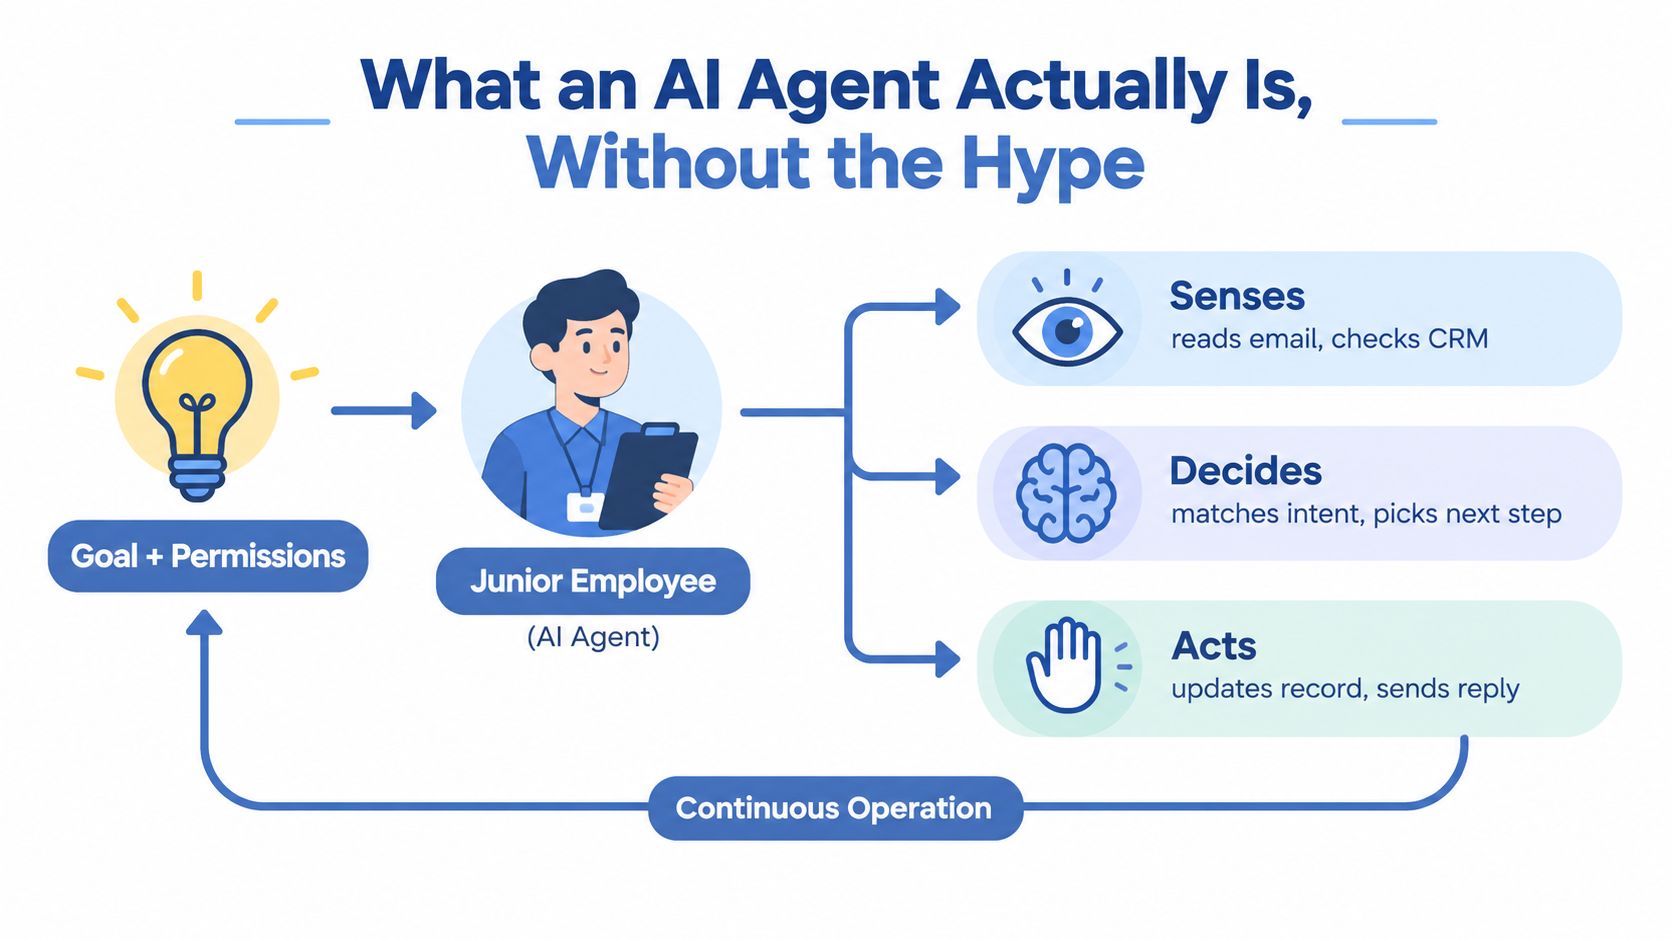
Think of an AI agent as a junior employee with a goal, a set of permissions, and access to tools. It reads context, chooses an action, checks the result, and continues until it reaches a stopping condition or asks for help.
A chatbot usually answers the next turn. An agent can continue working across a workflow.
The difference comes down to four practical abilities:
- Persistent memory: It can retain task state, such as which order it reviewed and which policy applied.
- Tool use: It can call Shopify, Gmail, Airtable, a CRM, a database, or another application instead of returning text alone.
- Multi-step planning: It can break a request into smaller actions and decide what to do after each result.
- Side effects: It can update a record, send a message, create a ticket, or issue a refund when its permissions allow it.
Here's a support example. A customer asks about a damaged order. A pre-filter can route messages containing “damaged” to a queue. A chatbot can explain the return policy. An agent can pull the order from Shopify, inspect fulfillment data, check the policy, compare the request against the order, draft a reply, and either send it or escalate it.
The rule-based pre-filter still has value. The agent layer earns its place only when the request requires several systems or decisions.
The three parts you need
Every useful agent has three components:
- An LLM brain that interprets language, weighs context, and selects the next step.
- A tool layer with explicit permissions that defines what the agent can read, write, send, or delete.
- An evaluation hook that logs each step, records the tool result, and lets you replay failures.
Without the log, you have a black box. Without scoped permissions, you have an employee who can touch every system. Without an evaluation hook, you can't tell whether an improvement came from a better prompt or a lucky test.
I'd still start with a contained workflow and read every tool call before granting write access.
Business Signals That Justify an AI Agent
Approve an agent when a workflow runs often, changes from case to case, and creates a measurable cost when handled manually. The PwC's survey summary from the opening provides enterprise context. For a small business, the decision is narrower: identify a repeated process where an agent can improve a result you already track.
Agent features are increasingly shipping inside the tools businesses already use. Shopify, help desks, CRMs, and research software may expose the actions you need, which can make a contained integration more sensible than building a separate system.
Five checks I use before approving an agent
| Signal | Threshold | Quick test |
|---|---|---|
| Interaction volume | Above 500 per week | If one template solves 60% of cases, start with a rule |
| Measurable outcome | A cost or revenue metric exists | Can you calculate cost per resolution or revenue per interaction? |
| Structured data | At least one readable and writable source | Can the system retrieve and update the record through an API? |
| Escalation path | A working human handoff exists | Can a person take over without reconstructing the whole case? |
| Error tolerance | A 5% to 15% error band is financially acceptable | Is a mistake cheaper than the current manual baseline? |
The volume threshold removes novelty from the business case. The metric separates results from activity. The data check exposes workflows still dependent on screenshots, memory, or scattered spreadsheets. If a team cannot answer these questions quickly, it is not ready to automate the process with an agent.
Use the Monday-morning test. Pull the last week of cases, count the total, mark how many required more than one system, record the current handling time, and calculate the cost of a wrong action. Then name the person who reviews exceptions. Those figures give you a pilot scope without relying on a model demo.
The error test forces an honest decision. An agent that drafts a low-risk internal summary can tolerate a different failure rate from one that changes a subscription or promises a refund. The acceptable band follows the workflow's downside, not the model's marketing page.
A workflow qualifies for an agent when you can describe its inputs, actions, output, owner, and failure cost on one page.
Clear anti-signals matter too. Novel creative work usually benefits from a prompt-and-edit loop. Low-volume, high-stakes decisions deserve human judgment. Any workflow where one wrong action costs more than ten correct actions should remain behind a review gate until testing proves the risk is manageable.
Agents vs Chatbots, Scripts, and Human-Only Work
Choose the lightest tool that meets the workflow's accuracy and latency requirement. An agent earns its place only when the process needs context, decisions, and actions across systems. More features do not justify more operational risk.
| Model | Average latency, illustrative planning range | Cost per task, illustrative planning range | Accuracy, illustrative planning range | Best fit |
|---|---|---|---|---|
| Human-only work | 8 to 40 minutes | $4 to $18 | 92% to 97% | Sensitive judgment and exceptions |
| Rule-based script | Under 1 second | Near-zero | Brittle when inputs vary | Stable fields and fixed rules |
| Conversational chatbot | 2 to 10 seconds | $0.10 to $0.80 | 75% to 88% | Natural-language answers without actions |
| AI agent | 15 to 90 seconds | $0.30 to $2.50 | 80% to 94%, with recovery from novel inputs | Multi-step decisions and tool use |
These figures are illustrative planning assumptions with no independent benchmark behind them. Use them to frame a decision conversation, then replace them with measurements from your own workflow before deployment.
A script wins when the task has fewer than five branching paths and zero external lookups. A chatbot fits when the process needs natural-language understanding but creates no side effect. An agent deserves a pilot when it must read context, select tools, act in multiple systems, and recover from unfamiliar inputs.
The operating cost is orchestration overhead. Benchmark reporting found that P95 latency for tool-using agent workflows ranged from about 8.9 seconds to 27.8 seconds, depending on the model. Another dynamic-reasoning benchmark attributed 69.4% of total latency to LLM inference and 30.2% to tool execution. Review the agent latency analysis before putting an agent on a customer-facing path.
Keep a decision record for each deployment. Samuel Woods's guide to AI agents versus chatbots applies the same rule: choose the smallest system that completes the job without creating a new support job for your team. If a script handles the workflow reliably, stop there. If a chatbot answers questions without changing records, do not add an agent. An agent is justified only when its added decisions and actions repay their latency, cost, and failure exposure.
A Readiness Framework You Can Run This Week
I adapted the readiness idea from IBM's work on workflow architecture, data interoperability, and enterprise orchestration, then reduced it to a check a solo operator can run in an afternoon. IBM identifies change management, AI governance, data governance, real-time data integration, interoperability, and financial integration as capabilities associated with autonomous workflow adoption. IBM's agentic AI operations report gives the larger operating model.
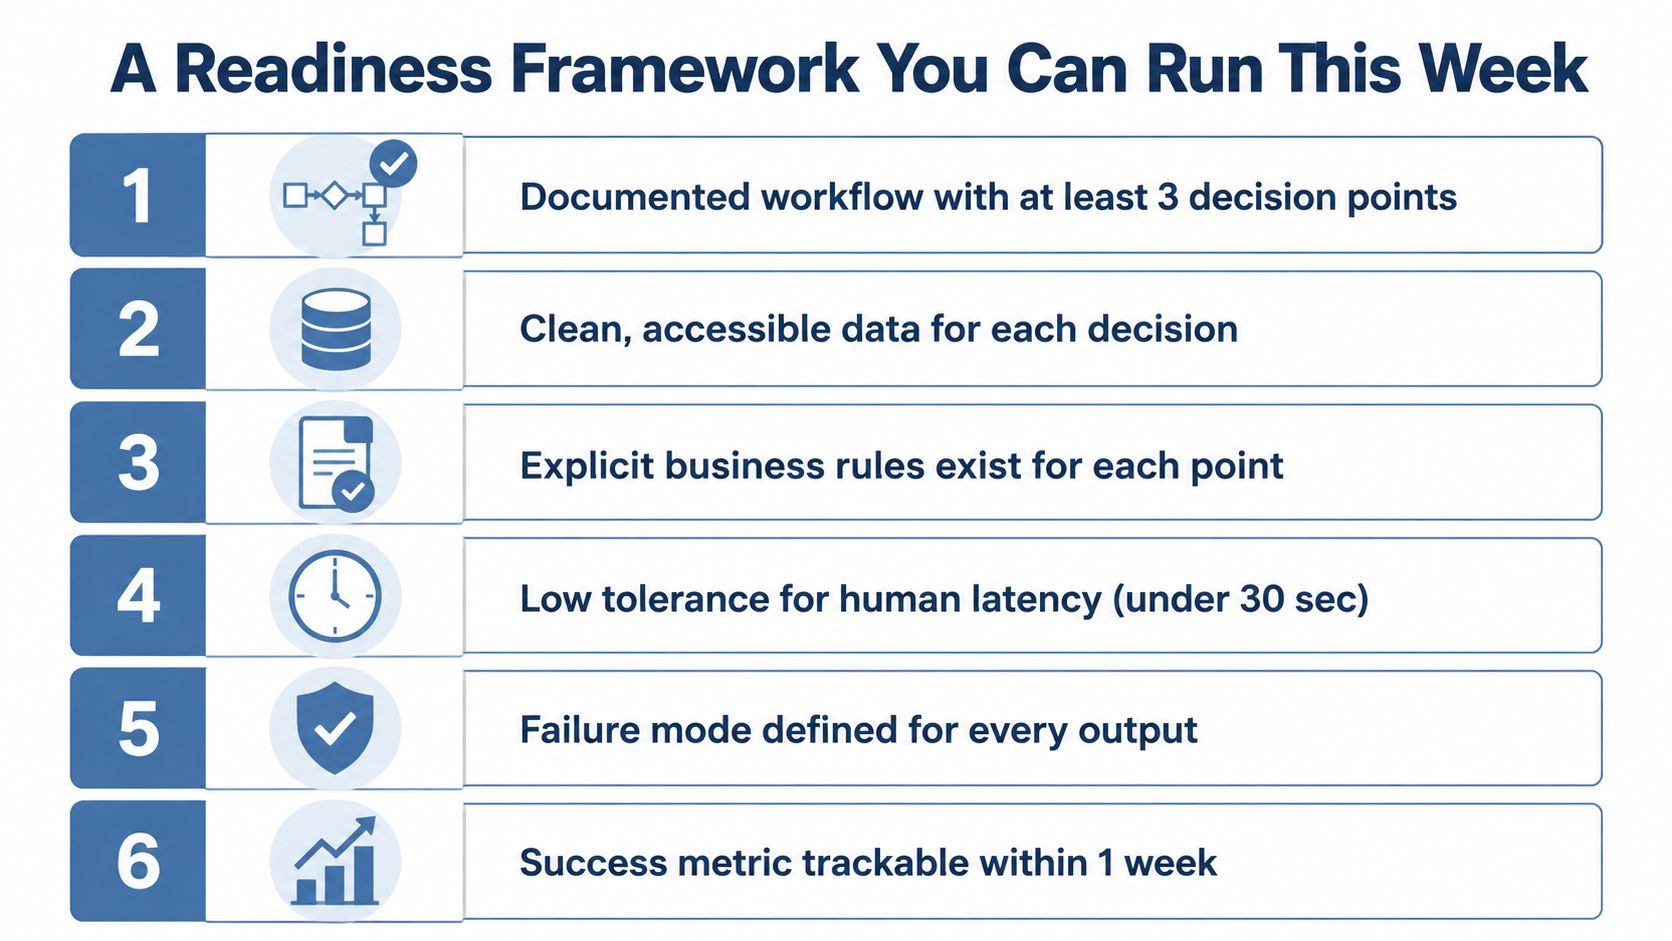
Score each item 0, 1, or 2. Zero means absent, one means partial, and two means proven.
The six checks
- Document the workflow. Write every step and record at least 50 weekly occurrences. A vague description such as “handle leads” scores zero.
- Check the data. Confirm that the agent can read and write the required source. Missing fields, stale exports, and unclear ownership score low.
- Define success. Pick one metric and record its baseline from the last 30 days. “Better support” isn't a metric. First-response time, cost per resolution, or qualified-lead routing time can be.
- Limit the blast radius. Keep failure below $200 or below two hours of rework for the first deployment. If one bad action exceeds that, add approval.
- Create an intercept point. A human must be able to pause, review, or take over the work.
- Log and replay. Store the input, selected tool, tool result, output, and final decision so you can inspect a failed run.
A lead-routing workflow might score 2 for documentation, 2 for data, 2 for a baseline, 1 for blast radius, 1 for human interception, and 1 for replay. That's 9 out of 12, enough to test in shadow mode.
A support triage workflow might score 1, 1, 1, 0, 1, and 1. That's 5 out of 12. Fix the data and routing logic first. A script or supervised chatbot is a better fit today.
Bain's adoption ladder separates information-retrieval agents, single-task agentic workflows, cross-system orchestration, and multi-agent constellations. I'd start at the first level that solves the problem, then move upward only after the previous level has a clean log and a stable metric.
For a practical deployment sequence, I keep this small-team AI agent guide beside the workflow map. The important part is the score, not the tool choice.
When AI Agents Are the Wrong Default
The productivity story leaves out the cost of failure. Independent analyses report that agents complete only about 30% to 35% of multi-step tasks in some studies. Another evaluation saw performance fall from an 86.9% pass rate under ideal conditions to 44.0% with perturbations, and a production-focused index tracked 60 incidents, including 40 high-severity or critical failures. These figures come from the agent failure analysis, and they're a reason to control the environment before expanding autonomy.
The first wrong fit is low-volume, high-stakes work. If you handle a handful of chargebacks, legal responses, medical claims, or financial decisions, a human review may cost less than building, monitoring, and repairing an agent.
The second is regulated work that requires deterministic evidence. A chain of probabilistic decisions can be difficult to explain after the fact. A fixed rule with a clear audit record may be less exciting and much easier to defend.
Five situations where I keep agents out
- Sub-second user experiences: Agents include reasoning, tool calls, file operations, and external waiting. Don't put one between a user action and a response that must feel immediate.
- One-off creative work: If you're writing one sales page or planning one campaign, prompt, edit, and approve it yourself.
- Dirty data: An agent will turn inconsistent fields into inconsistent actions. Clean the source before adding autonomy.
- Rare exceptions: If the workflow happens infrequently, you won't gather enough examples to evaluate it properly.
- Large downside: If one wrong action can erase the savings from many correct actions, require approval or keep the process human-led.
Human oversight also has limits. Across roughly 40,000 simulated agent runs, humans missed about one in three threatening commands, and in a browser-based test involving more than 409,000 approval decisions, reviewers approved roughly one-third of potentially malicious commands, according to research on agent permissions and human review. An approval button isn't a safety system by itself.
If the cost of being wrong exceeds the cost of a human doing the work, don't deploy an agent yet.
Your Monday Checklist and Governance Guardrails
You can test readiness before lunch without buying a large platform. I'd pick one workflow, document the current baseline, and keep the first version in shadow mode.
Eight actions for Monday
- Measure the baseline. Record hours spent per week and cost per resolution. Watch whether the manual estimate stays consistent.
- Score data freshness. Note when each source was last updated and count missing fields. Design the failure mode as “stop and escalate” when freshness fails.
- Define the blast radius. Write the maximum dollar loss and rework time you'll accept. Block writes that exceed it.
- Set a human checkpoint. Choose the exact step where you review before a refund, message, deletion, or external commitment.
- Run shadow mode. Let the agent make recommendations without taking action. Compare its decisions with your approved outcomes during a defined evaluation window.
- Log cost per resolution. Track model calls, tool calls, human review time, and downstream corrections. The metric is total cost, not token spend.
- Write the rollback runbook. Define the trigger, the person who disables the agent, and the manual process that takes over.
- Assign one owner. Put a name beside the workflow and review the dashboard on a fixed schedule. Shared ownership usually means no one notices the failure quickly.
I'd scope permissions by action, not by application. An agent that can read Shopify orders may not need permission to issue refunds. An agent that can draft Gmail messages may not need permission to send them.
For security guidance, read Anthropic's guidance on computer use and action controls and OpenAI's agent safety guidance. For a broader risk-management structure, use the NIST AI Risk Management Framework, then translate it into the specific tools, permissions, logs, and escalation rules you can maintain.
Current trace review also has a weakness. Research found that trace-based review can be verbose, cumbersome, and time-consuming, while participants missed small but consequential errors. A newer interface helped people find errors faster without meaningfully improving overall accuracy, according to the study of oversight interfaces. Your dashboard needs automatic checks, not only a long transcript for you to read.
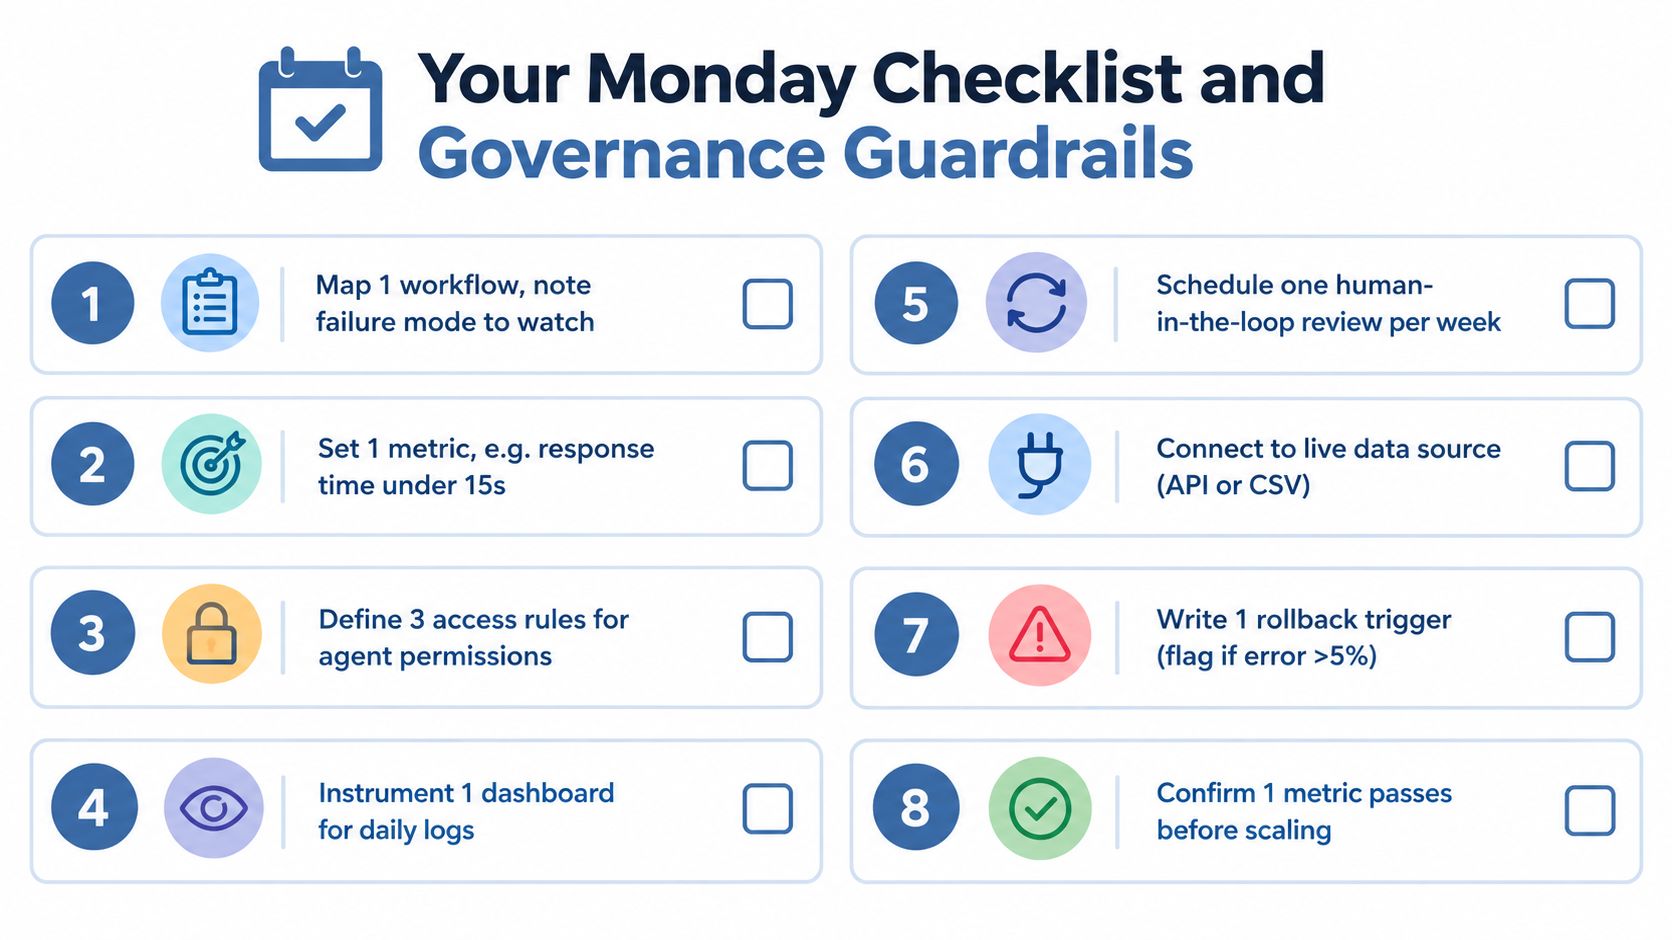
I track the economics in this AI agent ROI framework. Print a one-page version of your own checklist with the workflow, baseline, permissions, failure trigger, owner, and rollback steps. If you can't fill that page out, the process isn't ready for autonomy.
The Monday outcome should be modest: one mapped workflow, one metric, one safe test, and one clear reason to stop. That's enough to learn whether an agent saves time or just moves the work into debugging.
Frequently Asked Questions
What is the difference between an AI agent and a chatbot?
A chatbot usually answers the next turn in a conversation. An agent keeps working across a workflow: it holds task state, calls tools such as Shopify, Gmail or a CRM, breaks a request into steps, and can change records, send messages or issue refunds when its permissions allow. If the task needs language but no actions, a chatbot is usually the better fit.
How much volume justifies building an AI agent?
A useful filter is a workflow above 500 interactions a week with at least three decision branches, a measurable downstream cost, and APIs you can debug. If a single template solves around 60% of cases, start with a rule instead. These thresholds are an operating filter rather than a law, so replace them with numbers from your own last week of cases.
When should you use a script instead of an AI agent?
Use a script when the task has fewer than five branching paths and needs no external lookups. Rule-based scripts respond in under a second at near-zero cost, but they break when inputs vary. Choose the lightest tool that meets the workflow’s accuracy and latency requirement, and add an agent only when the process needs context, decisions and actions across several systems.
When is an AI agent the wrong choice?
Keep agents out of low-volume, high-stakes work such as chargebacks or legal responses, regulated work that needs deterministic evidence, sub-second user experiences, one-off creative tasks, workflows fed by dirty data, and rare exceptions you cannot collect enough examples to evaluate. If one wrong action costs more than a human doing the work, do not deploy an agent yet.
How do you test whether a workflow is ready for an AI agent?
Score six checks from 0 to 2: a documented workflow with at least 50 weekly occurrences, readable and writable data, one success metric with a 30-day baseline, a blast radius below $200 or two hours of rework, a human intercept point, and full logging for replay. A score around 9 out of 12 is enough to test in shadow mode.
Is human approval enough to make an AI agent safe?
No. Across roughly 40,000 simulated agent runs, humans missed about one in three threatening commands, and reviewers in a browser test approved roughly a third of potentially malicious commands. Scope permissions by action rather than by application, block writes that exceed your blast radius, write a rollback runbook, and add automatic checks instead of relying on someone reading long transcripts.